THE SHORT VERSION
This new AI spits out 1,000 tokens a second — and still beats GPT-6 Luna
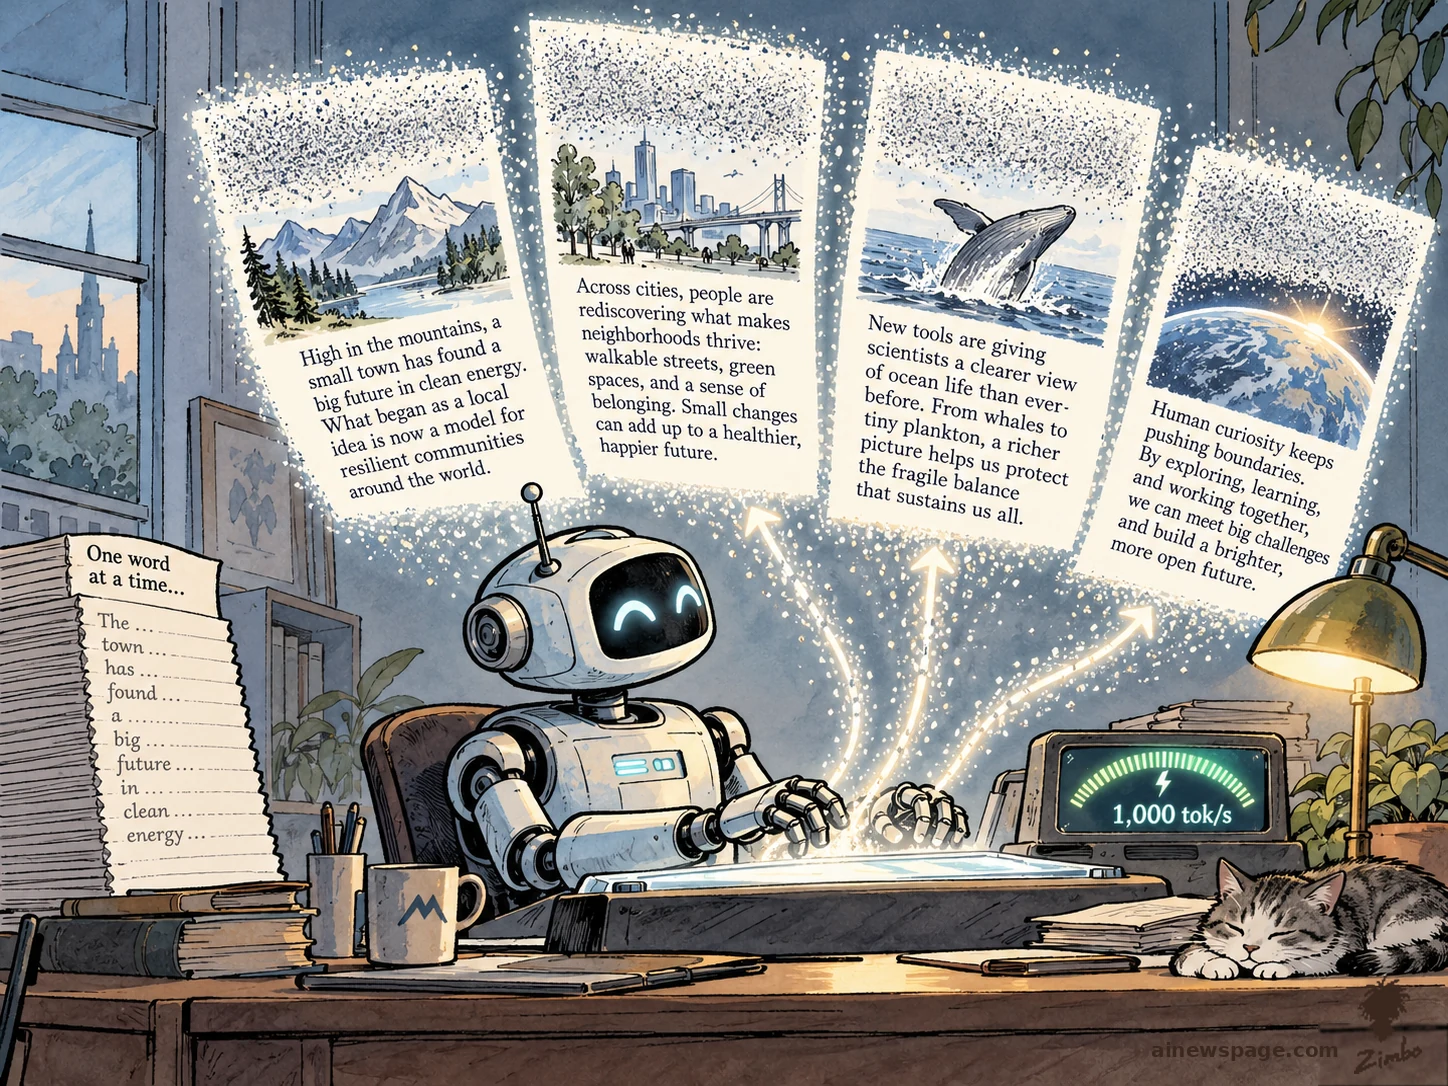
Inception has released Mercury 3, a diffusion language model that generates text by refining many tokens in parallel instead of predicting one at a time. The company says it produces more than 1,000 tokens per second on widely available NVIDIA GPUs, with a context window of 1 million tokens — up from 260,000 in Mercury 2.5.
Inception claims Mercury 3 outperforms speed-optimized rivals GPT-6 Luna and Claude Haiku 5.5 on a range of benchmarks while running four to eight times faster, and that it is more than 40 times larger than its first-generation Mercury 1 at comparable speeds. Those benchmark results are the company's own.
The model is aimed at uses where delay compounds — interactive tutoring, live translation, writing assistants and software agents. Early customer RevisionDojo reports student feedback responses in about one second. Mercury 3 is available through the Inception API, Baseten, OpenRouter and Vercel.