THE SHORT VERSION
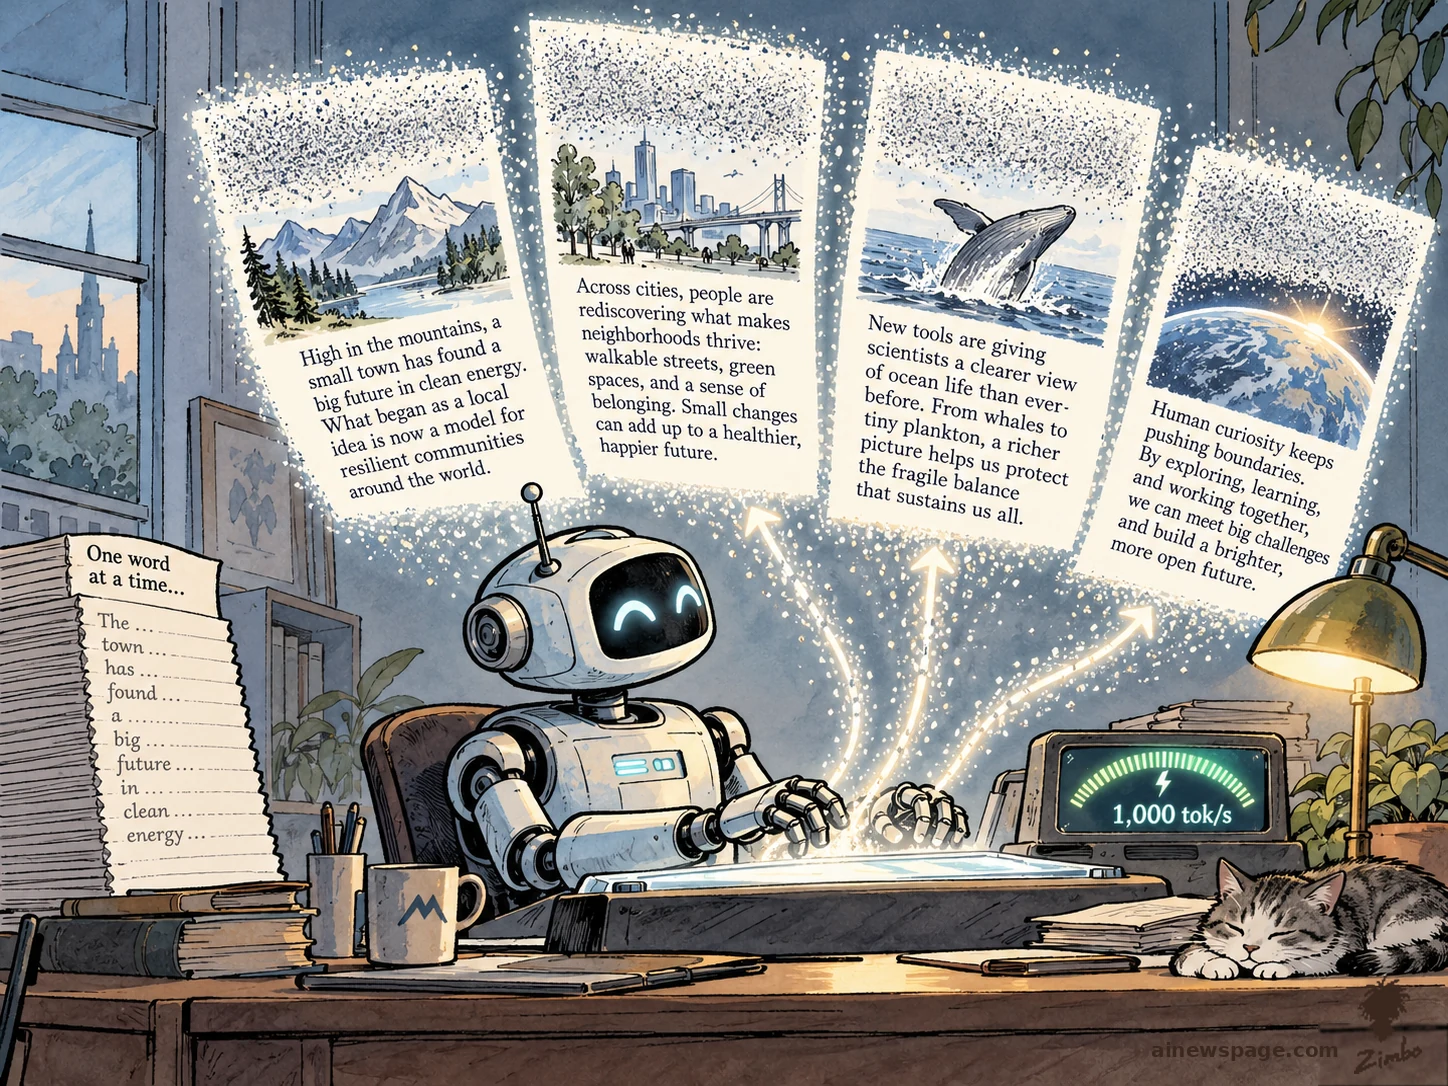
Mercury 3 is a diffusion model: it writes paragraphs in parallel, like a photo resolving from noise
Mercury 3, Inception's fourth diffusion language model, starts from a rough draft of a full answer and refines every position in parallel over a few passes, rather than generating token by token. Inception reports 1,068 tokens per second on NVIDIA GPUs and a 1M-token context window; the model is API-only, with no open weights.
On Inception's own benchmark table, at medium settings, Mercury 3 leads GPT-6 Luna and Claude Haiku 5.5 on 8 of 12 tests. Its biggest wins are SWE-Bench Atlas at 51.08, about 18 points ahead of both rivals, and IFBench at 76.84. Haiku 5.5 still beats it on DeepSWE v1 and on long-context retrieval in MRCR v2.
List pricing is $0.20 per million input tokens and $0.70 per million output, halved at launch, with new accounts getting 100M free tokens. Inception also released two siblings: Mercury Voice for voice agents and Mercury Decide for classification.