THE SHORT VERSION
Mercury 3 is a diffusion model: it writes paragraphs in parallel, like a photo resolving from noise
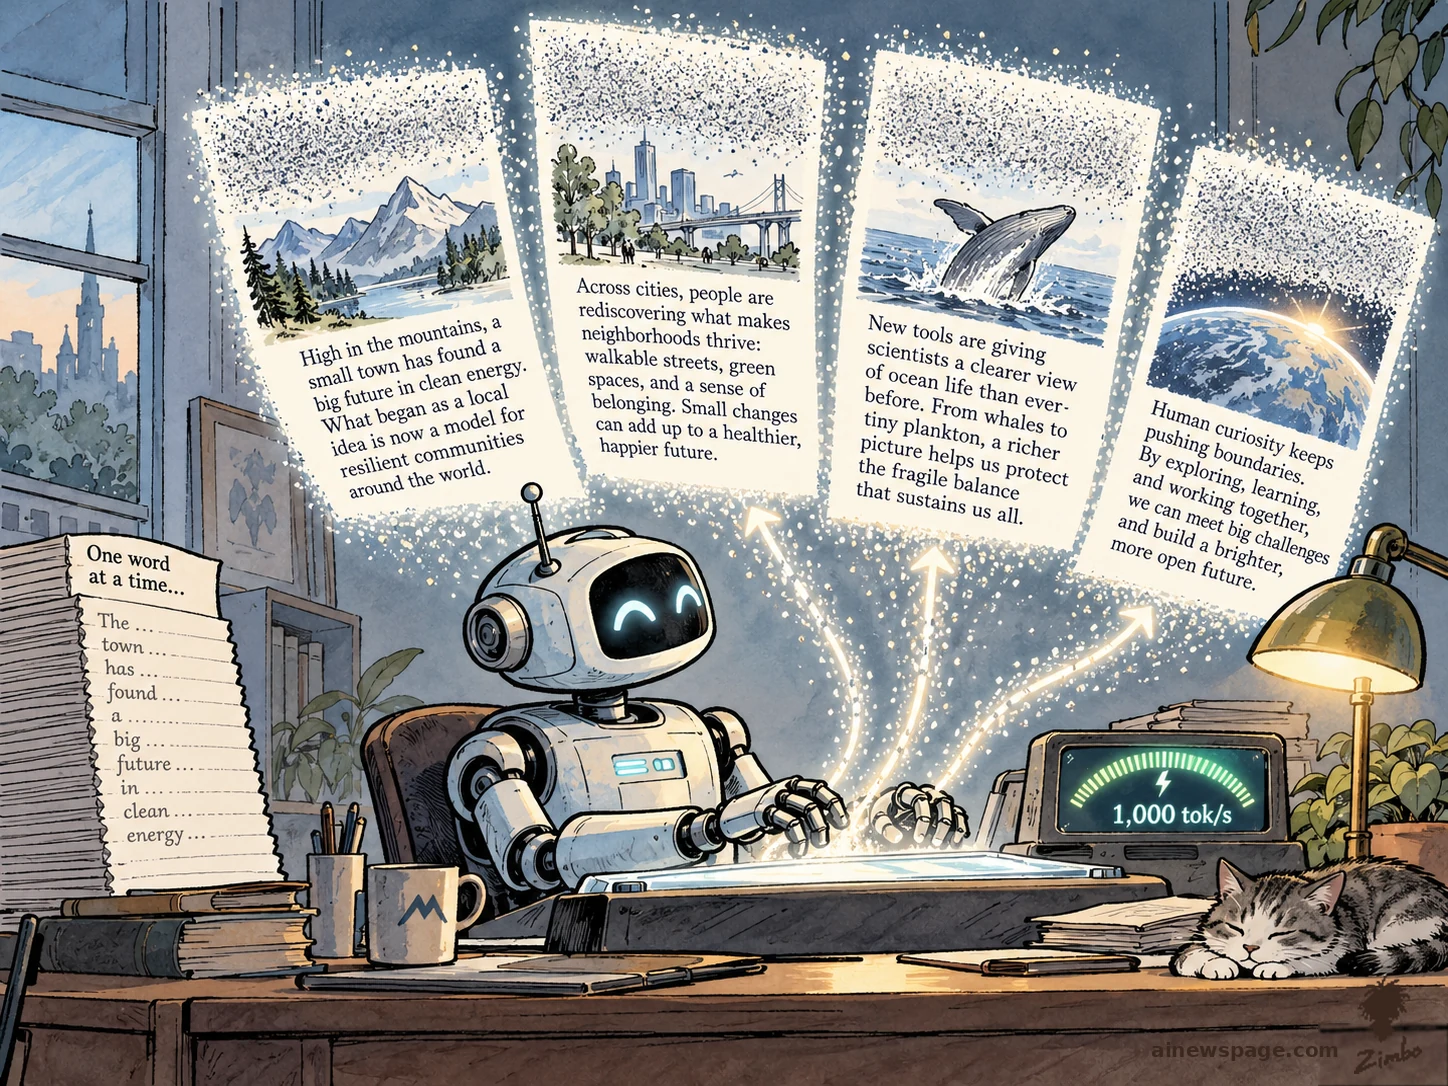
Mercury 3 differs from conventional language models in how it writes. Autoregressive models produce one token at a time, while a diffusion model drafts and refines groups of tokens in parallel through iterative denoising, in a process coverage likens to a photograph resolving from noise. Inception argues that parallelism is why speed can be maintained as the model grows.
A MarkTechPost breakdown summarised in coverage had Mercury 3 ahead of GPT-6 Luna and Claude Haiku 5.5 on eight of twelve tests at medium settings, including SWE-Bench Atlas at 51.08, roughly eighteen points ahead of both rivals, while trailing Haiku 5.5 on DeepSWE v1 by about five points. The model offers a one-million-token context window and, according to Inception, stays above 1,000 tokens per second on widely available Nvidia hardware.