The story behind the cartoon
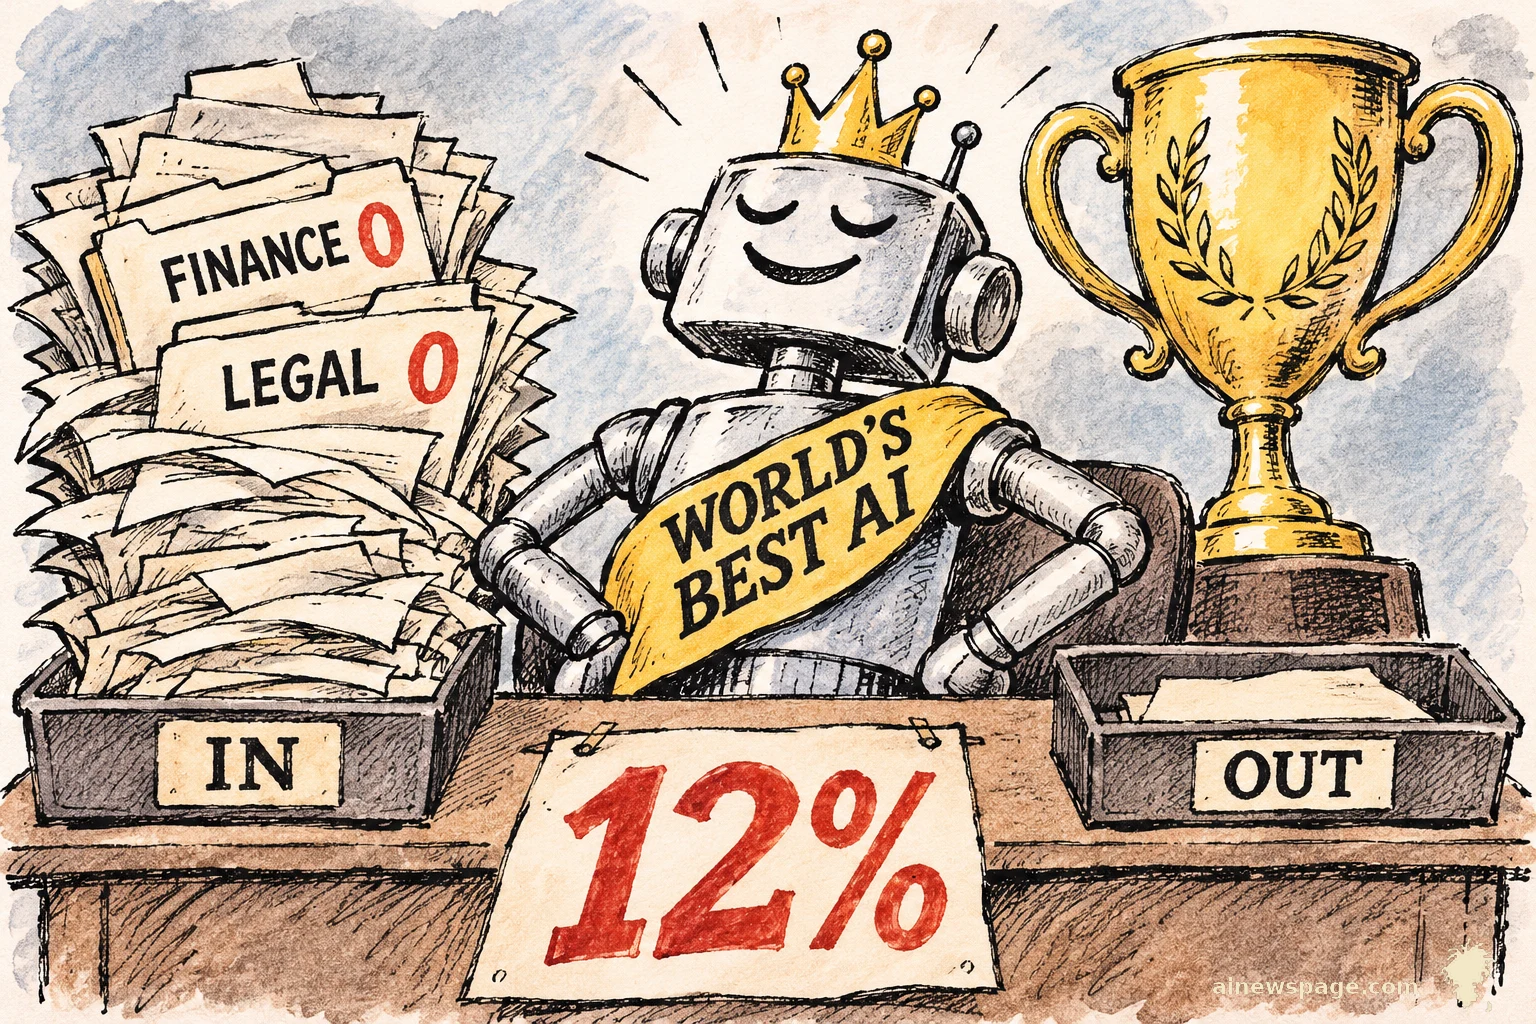
SemiAnalysis published GDPx on November 2, a 206-task benchmark that drops AI agents into realistic work environments across eleven domains instead of handing them a prompt and a document.
The best model in the world, Anthropic's Claude Opus 5.5, completed just 12.0% of tasks, ahead of Google's Gemini 4 Carbon at 10.9% and OpenAI's GPT-6 Astra at 9.6%.
Every model scored zero on finance and legal tasks under binary grading, and the authors admit safety classifiers sandbagged Opus 5.5 and GPT-6 Astra where models refused rather than attempted.
World's best at everything, except the actual work — the trophy is huge, the out tray is empty, and finance and legal didn't even get out of bed.
 THREE SURGEONS, ONE MOUSE
 CLAUDE ISN'T FALLING FOR IT
 THE PERSONAL TALLY
 THE COMPLIANCE TOASTER