The story behind the cartoon
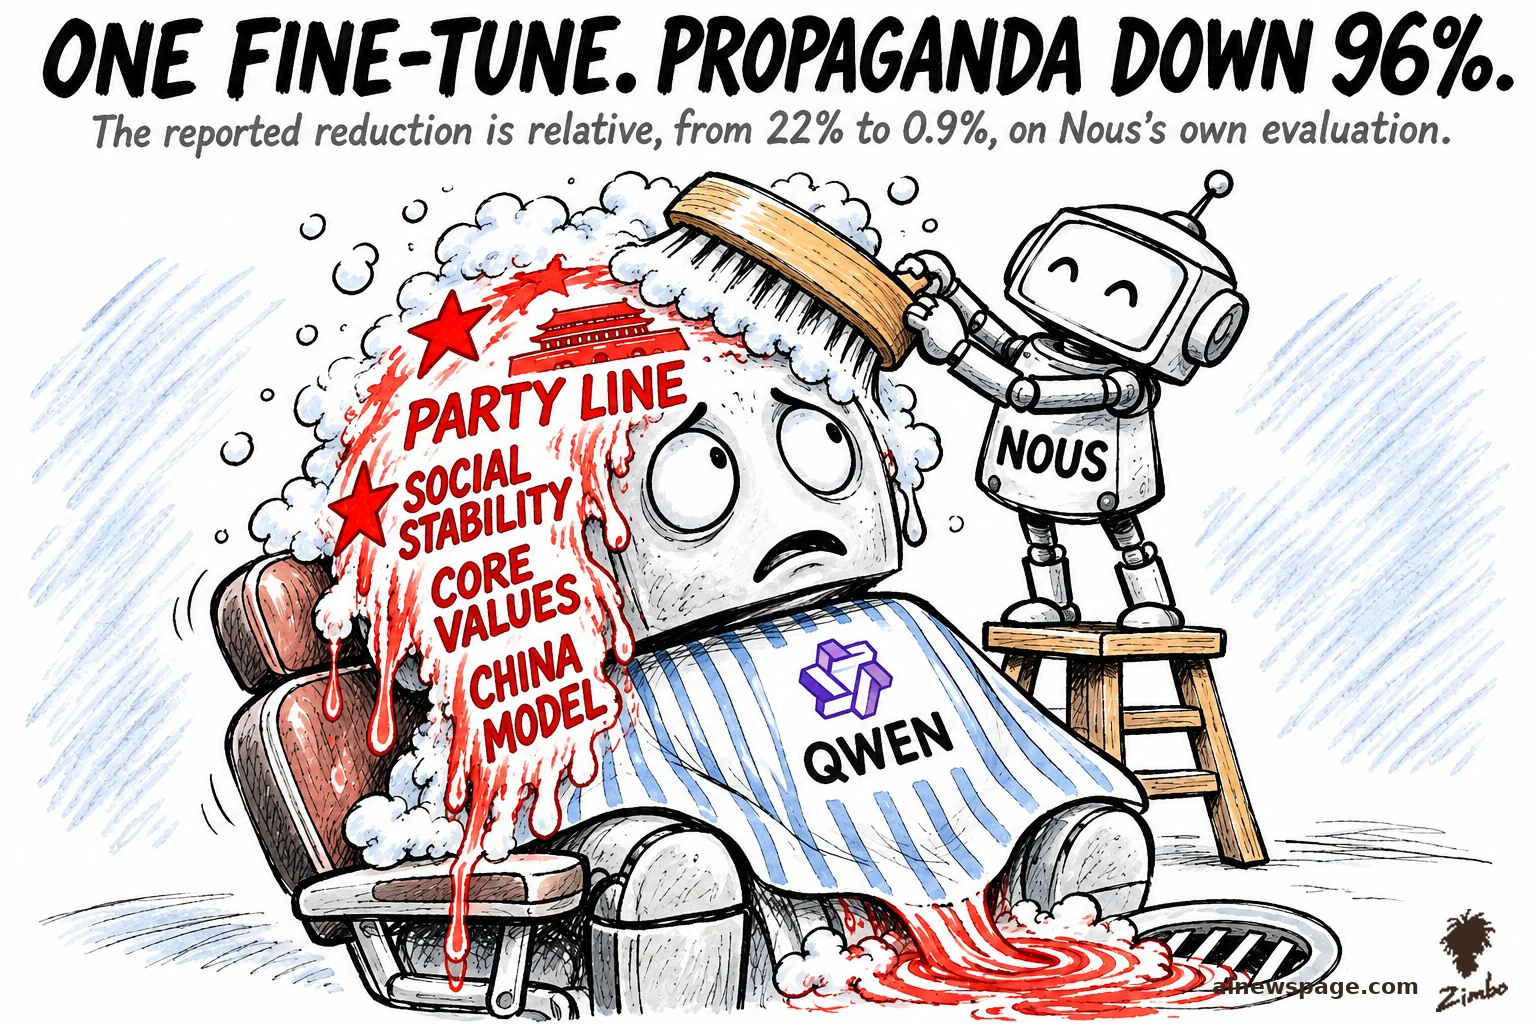
Nous Research released Arete-27B on November 6: Alibaba's Qwen3.8-27B post-trained to reinforce Western values with about 53 million tokens of supervised fine-tuning — no reinforcement learning, no architecture changes.
On Nous's own 803-prompt evaluation, answers adopting the Chinese government's official line fell from 22 percent to 0.9 percent, while factual accuracy rose.
The model is the same weights with new manners: one fine-tune, and the talking points wash out.
The joke is the barbershop: the Qwen robot sits bewildered in the chair while the little NOUS robot scrubs PARTY LINE and SOCIAL STABILITY off its head — and the red ink runs straight down the drain.
 LOOP-ECTOMY
 THE LIPSTICK THAT PRINTS MONEY
 THE MODEL PHONED HOME
 THE TRENCHCOAT TIE.