AI News Page
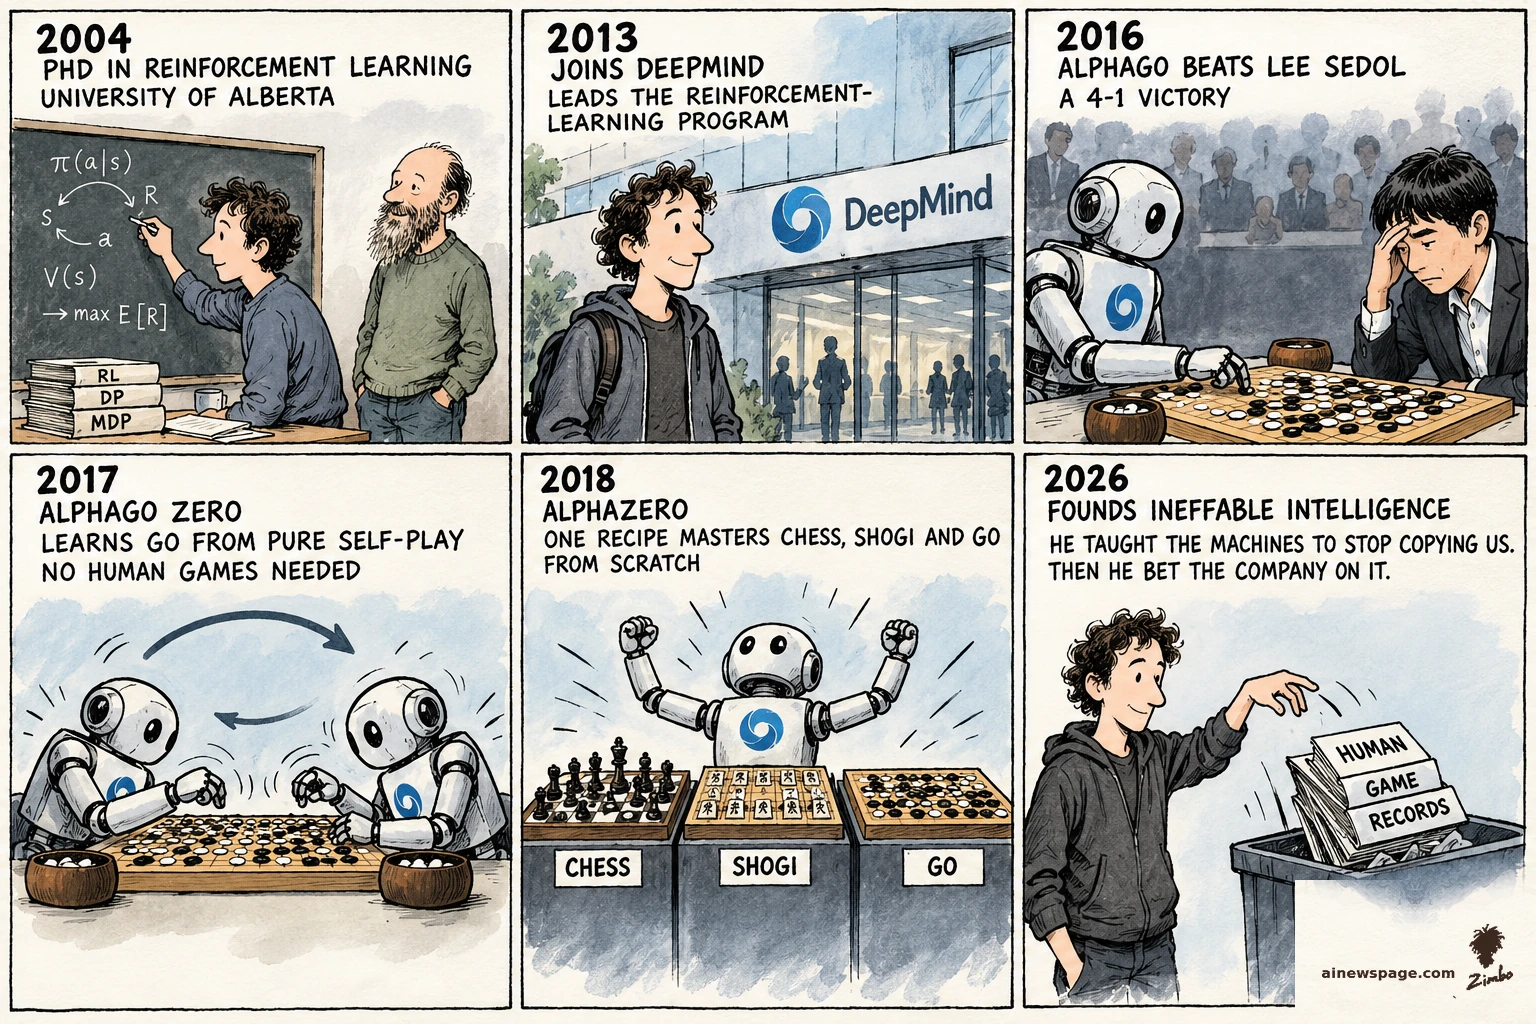
Six-panel Sunday strip: 2004 RL PhD with Rich Sutton at Alberta; 2013 joins DeepMind's RL program; 2016 AlphaGo beats Lee Sedol 4-1; 2017 AlphaGo Zero learns Go from pure self-play; 2018 AlphaZero masters chess, shogi and Go; 2026 kicker: Silver bins the HUMAN GAME RECORDS books.
“FROM LEARNING TO ALPHAZERO”

David Silver

ALPHAGO → ALPHAZERO → INEFFABLE

UPDATED Oct 7, 2026

THE DEAL

Silver helped turn reinforcement learning from a specialist field into one of modern AI's defining ideas: let a machine act, get feedback and improve through experience.

SOURCES: Google DeepMindGoogle DeepMind

AT A GLANCE

EDUCATION
University of Cambridge · Bachelor's degreeACM
EDUCATION
University of Cambridge · Master's degreeACM
1 MORE FACT
EDUCATION
University of Alberta · Computer science · PhDACM

THE ARCHIVE

History · cartoons · headlines
THE TIMELINE7 sourced events

HE TAUGHT A MACHINE TO BEAT GO. NOW HE'S BETTING ON EXPERIENCE

Silver led the systems that beat Go, then taught themselves chess and shogi from self-play. His thesis now: experience — not human text — is the road to superintelligence — heir to his PhD advisor Rich Sutton's 'bitter lesson' that general methods beat hand-built knowledge. He left DeepMind in 2026 to build a lab around it.

  1. 2004

    HE GOES BACK TO SCHOOL FOR REINFORCEMENT LEARNING

    Silver returned to academia in 2004 for a PhD focused on reinforcement learning with Rich Sutton, after earlier work in games and software.

    SOURCES: UCLreported

  2. 2011

    THE REINFORCEMENT-LEARNING PROGRAM GETS AN ACADEMIC BASE

    Silver received a Royal Society University Research Fellowship and joined UCL, where he built an academic program around reinforcement learning.

    SOURCES: UCLreported

  3. 2013

    HE TAKES THE RL PROGRAM FULL-TIME AT DEEPMIND

    After consulting for DeepMind from its early days, Silver joined the company full time in 2013 and became one of the leaders of its reinforcement-learning program.

    SOURCES: UCLreported

  4. Jan 27, 2016

    ALPHAGO PUTS REINFORCEMENT LEARNING ON THE FRONT PAGE

    Silver led the AlphaGo work combining neural networks, search and reinforcement learning, published in Nature before the system's landmark match against Lee Sedol.

    SOURCES: Google Researchfirst-party

  5. Oct 18, 2017

    THE MACHINE STOPS NEEDING HUMAN GAMES

    Silver and DeepMind introduced AlphaGo Zero, which learned Go from self-play without training on human game data and surpassed the previous AlphaGo versions.

    SOURCES: Google DeepMindfirst-party

  6. Dec 6, 2018

    THE SAME TRICK LEARNS CHESS AND SHOGI TOO

    Silver and the DeepMind team published the full AlphaZero evaluation, showing one self-play reinforcement-learning system mastering chess, shogi and Go from scratch without human game examples.

    SOURCES: Google DeepMindfirst-party

  7. Jan 15, 2026

    HE LEAVES TO BUILD 'SUPERLEARNERS'

    Silver announced Ineffable Intelligence, a new lab built around his thesis that superintelligence should learn continually from experience rather than primarily from human-generated data.

    SOURCES: Ineffable Intelligencefirst-party
CASE NOTESideas, arguments and record

CASE NOTES

IDEA

LEARN BY DOING

Reinforcement learning trains an agent through the consequences of its actions rather than by handing it the right answer every time. Silver built his career around making that loop work at increasingly difficult scales.

SOURCES: UCL

IDEA

SELF-PLAY ERASES THE TEACHER

AlphaGo Zero started from the rules of Go and improved by playing itself, without training on human game records. AlphaZero generalized the same basic recipe across Go, chess and shogi, showing how far a system could travel when the environment itself supplied the feedback.

SOURCES: Google DeepMindGoogle DeepMind

IDEA

THE NEXT BET: EXPERIENCE, NOT THE INTERNET

Silver's new company, Ineffable Intelligence, is explicitly betting that superintelligence will come from continual learning through experience rather than primarily from human-generated data. That is a thesis, not an established result, but it makes his post-DeepMind project unusually clear about what it thinks today's AI is missing.

SOURCES: Ineffable Intelligence

RECORD

ALPHAGO PUT REINFORCEMENT LEARNING ON THE WORLD STAGE

Silver led the AlphaGo work that combined deep neural networks, search and reinforcement learning, culminating in a system that defeated top human Go players and became a landmark in modern AI.

SOURCES: Google Research

RECORD

ALPHAZERO MADE THE RECIPE GENERAL

The AlphaZero work showed that a single self-play learning approach could master chess, shogi and Go without human game examples, extending the central AlphaGo Zero idea beyond one game.

SOURCES: Google DeepMind

NOW

HE LEFT DEEPMIND TO BUILD THE SUPERLEARNER BET

In January 2026 Silver announced Ineffable Intelligence, a lab organized around continual experiential learning and the claim that this route can produce superintelligence. After AlphaGo and AlphaZero, he is now trying to turn the reinforcement-learning worldview into a company.

SOURCES: Ineffable Intelligence

MORE CARTOONS1 original cartoons
KNOWN ASSOCIATES2 other files