Chris Olah
OPEN THE BLACK BOX
THE DEAL
Olah took a Thiel Fellowship instead of a normal academic track and spent years inventing ways to see inside neural networks.
AT A GLANCE
- EDUCATION
- University of Toronto · Mathematics · left without a degree after about one yearFortune
THE ARCHIVE
History · cartoons · headlines
THE TIMELINE8 sourced events
THE GUY WHO DRAWS WHAT'S INSIDE THE MACHINE
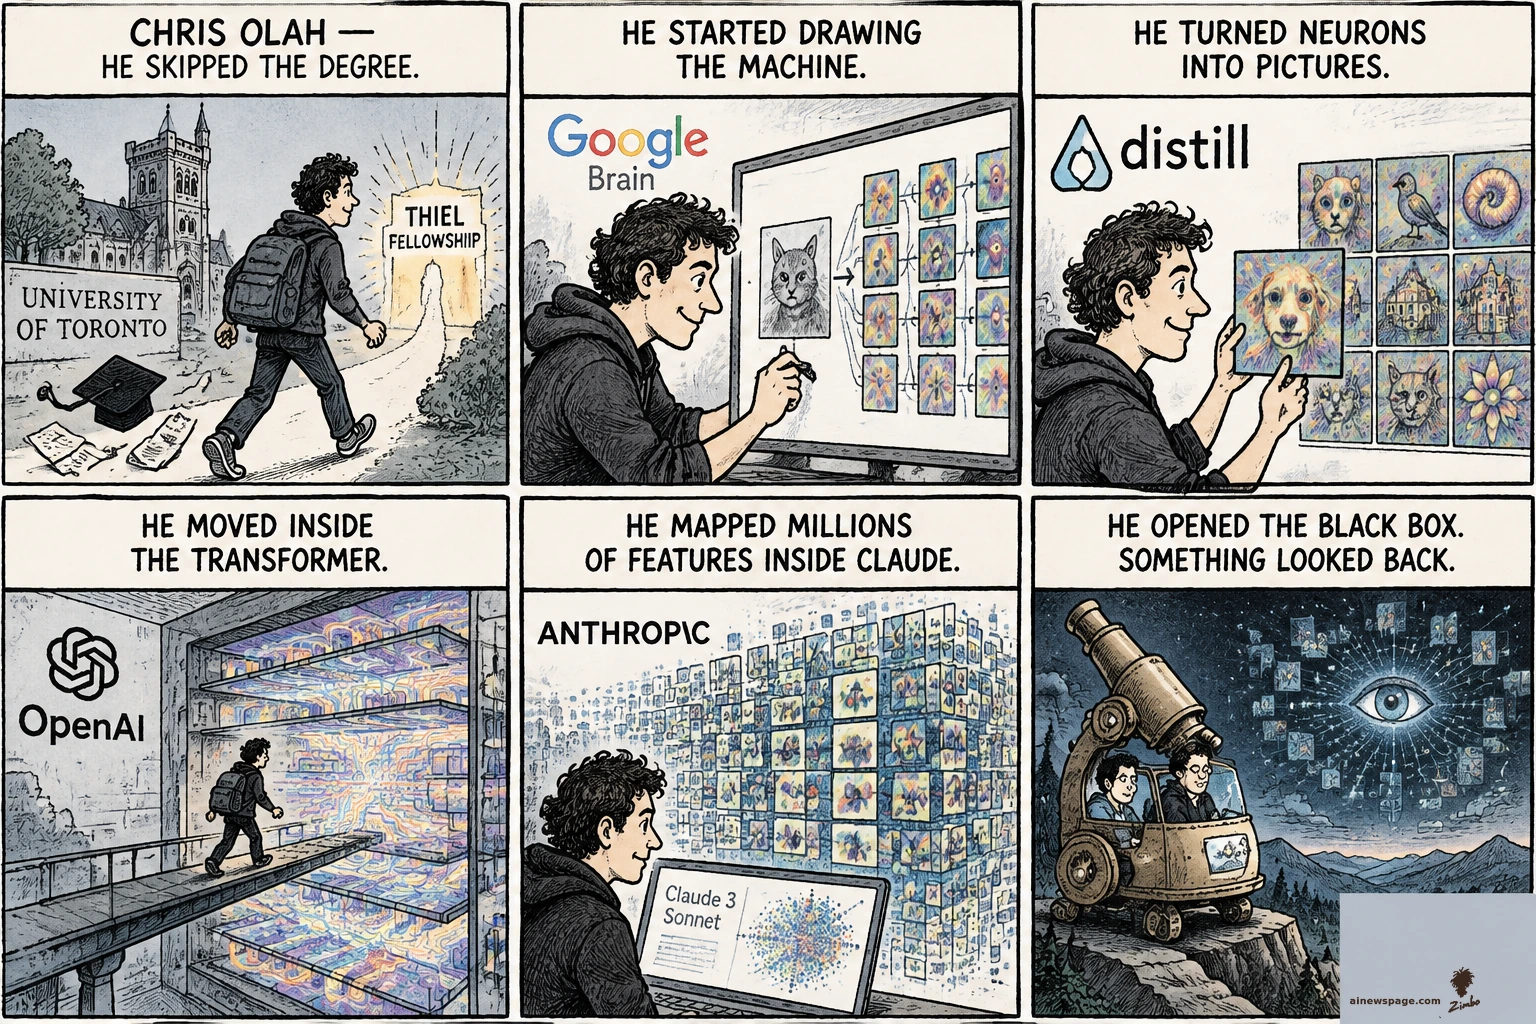
Olah took a Thiel Fellowship instead of a normal academic track and spent years inventing ways to see inside neural networks. The work ran through Google Brain, Distill — the interactive-explanation journal he co-founded — and OpenAI's Circuits program that christened the field 'mechanistic interpretability', and now leads the Anthropic team mapping millions of internal features inside Claude.
Jul 2012
HE TAKES A THIEL FELLOWSHIP INSTEAD OF A NORMAL ACADEMIC TRACK
Olah's own CV records a Thiel Fellowship beginning in 2012, part of an unusually independent path into machine learning rather than a conventional university research career.
SOURCES: Chris Olahfirst-party
Jul 2014
GOOGLE BRAIN LETS HIM START DRAWING NEURAL NETWORKS
Olah joined Google Brain as an intern and worked on interactive visualization of neural networks, turning his visual and explanatory instincts into the interpretability program that followed.
SOURCES: Chris Olahfirst-party
Sep 8, 2016
HE STARTS DRAWING THE MACHINE'S INTERNAL LOGIC
At Google Brain, Olah published a visual exploration of attention and augmented recurrent neural networks, part of a broader effort to make neural systems understandable by inspection.
SOURCES: Distillfirst-party
Nov 7, 2017
HE TURNS NEURONS INTO PICTURES PEOPLE CAN READ
Olah and collaborators published 'Feature Visualization,' a widely used framework for showing what image-network units respond to across layers.
SOURCES: Distillfirst-party
Apr 14, 2020
OPENAI PUTS THE CIRCUITS UNDER A MICROSCOPE
Olah contributed to OpenAI Microscope, a collection of visualizations meant to let researchers inspect the internal features and circuits of vision models.
SOURCES: OpenAIfirst-party
2021
INTERPRETABILITY MOVES INTO TRANSFORMERS
Olah and collaborators published a mathematical framework for transformer circuits, extending mechanistic-interpretability methods from vision systems into attention-based language models.
SOURCES: Transformer Circuitsfirst-party
May 21, 2024
ANTHROPIC MAPS MILLIONS OF FEATURES INSIDE CLAUDE
Anthropic researchers used sparse autoencoders to extract and map millions of concepts represented inside Claude 3 Sonnet, a major scale-up of Olah's interpretability program.
SOURCES: Anthropicfirst-party
Jul 6, 2026
THE LAB FINDS A 'GLOBAL WORKSPACE' PATTERN IN LANGUAGE MODELS
Anthropic published evidence for a global-workspace-like mechanism in language models, continuing the effort to explain model computation through identifiable internal structures.
SOURCES: Anthropicfirst-party
MORE CARTOONS1 original cartoons