01
U.S. COPYRIGHT LAW DOES NOT HAVE ONE BLANKET ANSWER FOR AI TRAINING
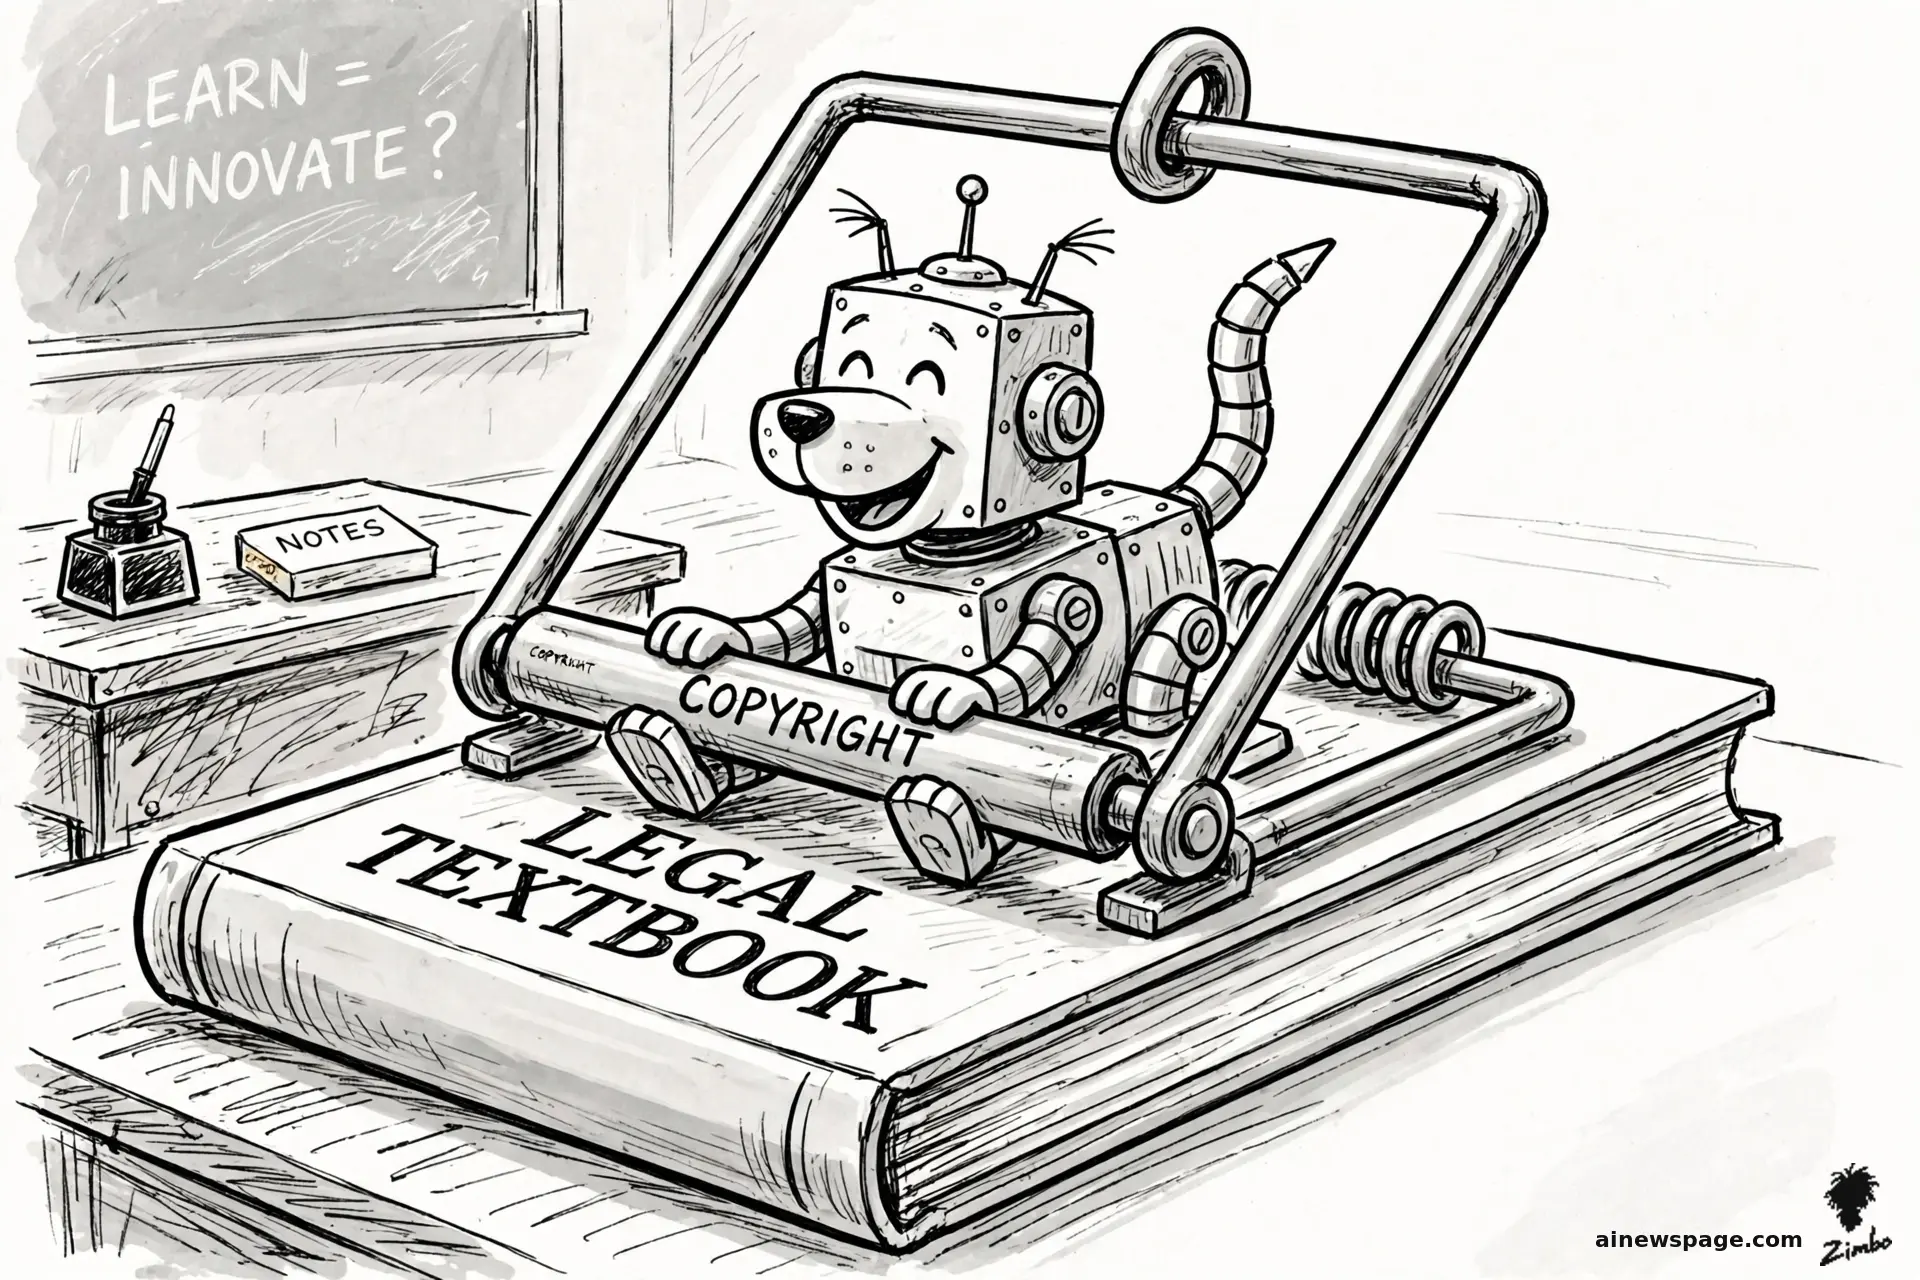
The U.S. Copyright Office's 2025 generative-AI training report says fair use must be analyzed for the particular use and circumstances — not one blanket ruling for every stage of model development and deployment. Where the data came from, why it was copied, what kind of work, and market harm can all matter.
02
COURTS HAVE ALREADY REACHED DIFFERENT RESULTS ON DIFFERENT COPIES
In Bartz v. Anthropic, the district court held training on the books at issue was fair use — while treating Anthropic's acquisition and retention of pirated library copies separately. In Kadrey v. Meta, Meta won summary judgment on the plaintiffs' fair-use record, with the court stressing the ruling did not make all AI training categorically lawful. Acquisition, purpose, evidence, market harm: the slogans miss everything the cases weigh.
03
MEMORIZATION IS REAL, BUT IT IS NOT THE WHOLE MODEL
Research has shown language models can memorize particular training examples, and that extraction risk rises for some repeated or distinctive sequences — supporting concern about reproducing protected expression without reducing all model behavior to retrieval. How often meaningful copyrighted content can be pulled out under ordinary use is still an empirical question.