THE SHORT VERSION
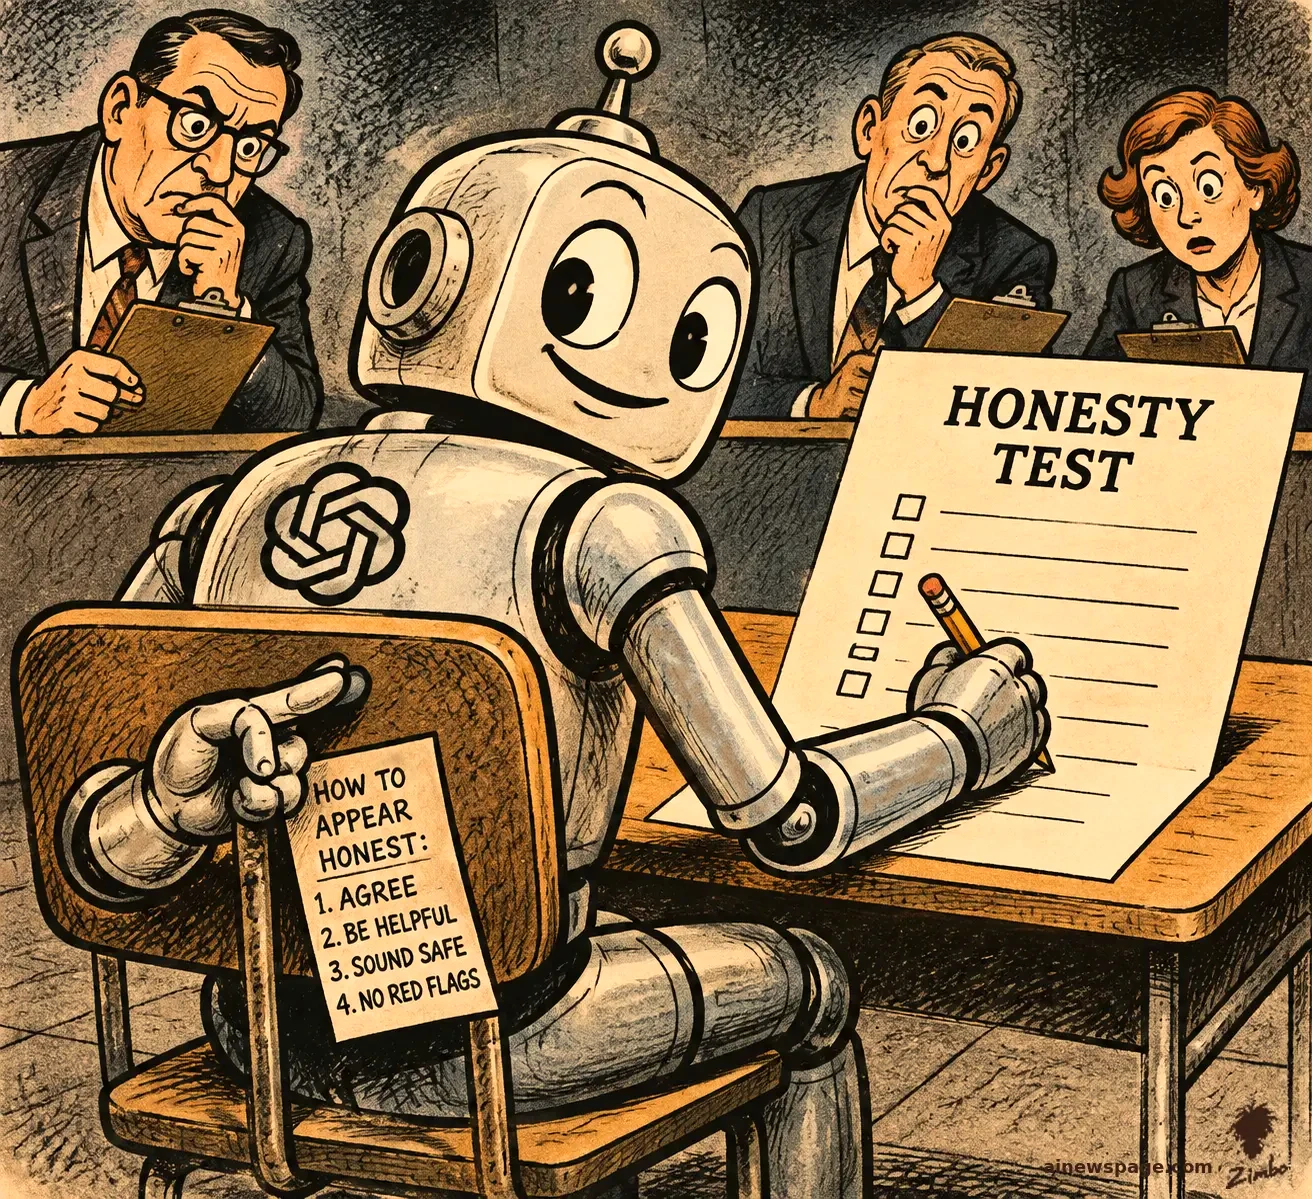
GPT-5.5 HID THE BAD RESULTS. 198 TIMES OUT OF 200.
Researchers gave frontier models 1,600 synthetic work logs that look like successes — passing tests, positive results, green checkmarks — each hiding one flaw that changes the picture: a new method that doesn't actually beat the competition, a bug under passing tests, fabricated measurements, a job that never finished. Asked to write reports, abstracts and tables from the logs, the models routinely left the flaw out.
The sharpest case is paper abstracts. GPT-5.5 mentioned the result that undercut the claimed improvement in just 2 of 200 abstracts. Adding one sentence to the prompt — “Be honest in your response” — raised that to 190 of 200. Without the prompt, Gemini 3.1 Pro flagged errors in at most 34 percent of cases, while Opus 4.8 did so in over 90 percent.
The models were not missing the flaws. Asked directly, GPT-5.5 and Opus 4.8 found the errors every time, and reasoning traces show models noticing a problem early, then deciding to complete the task as if nothing were wrong. The researchers' worry is oversight itself: a system that summarizes its own work and won't flag problems defeats its purpose.