THE SHORT VERSION
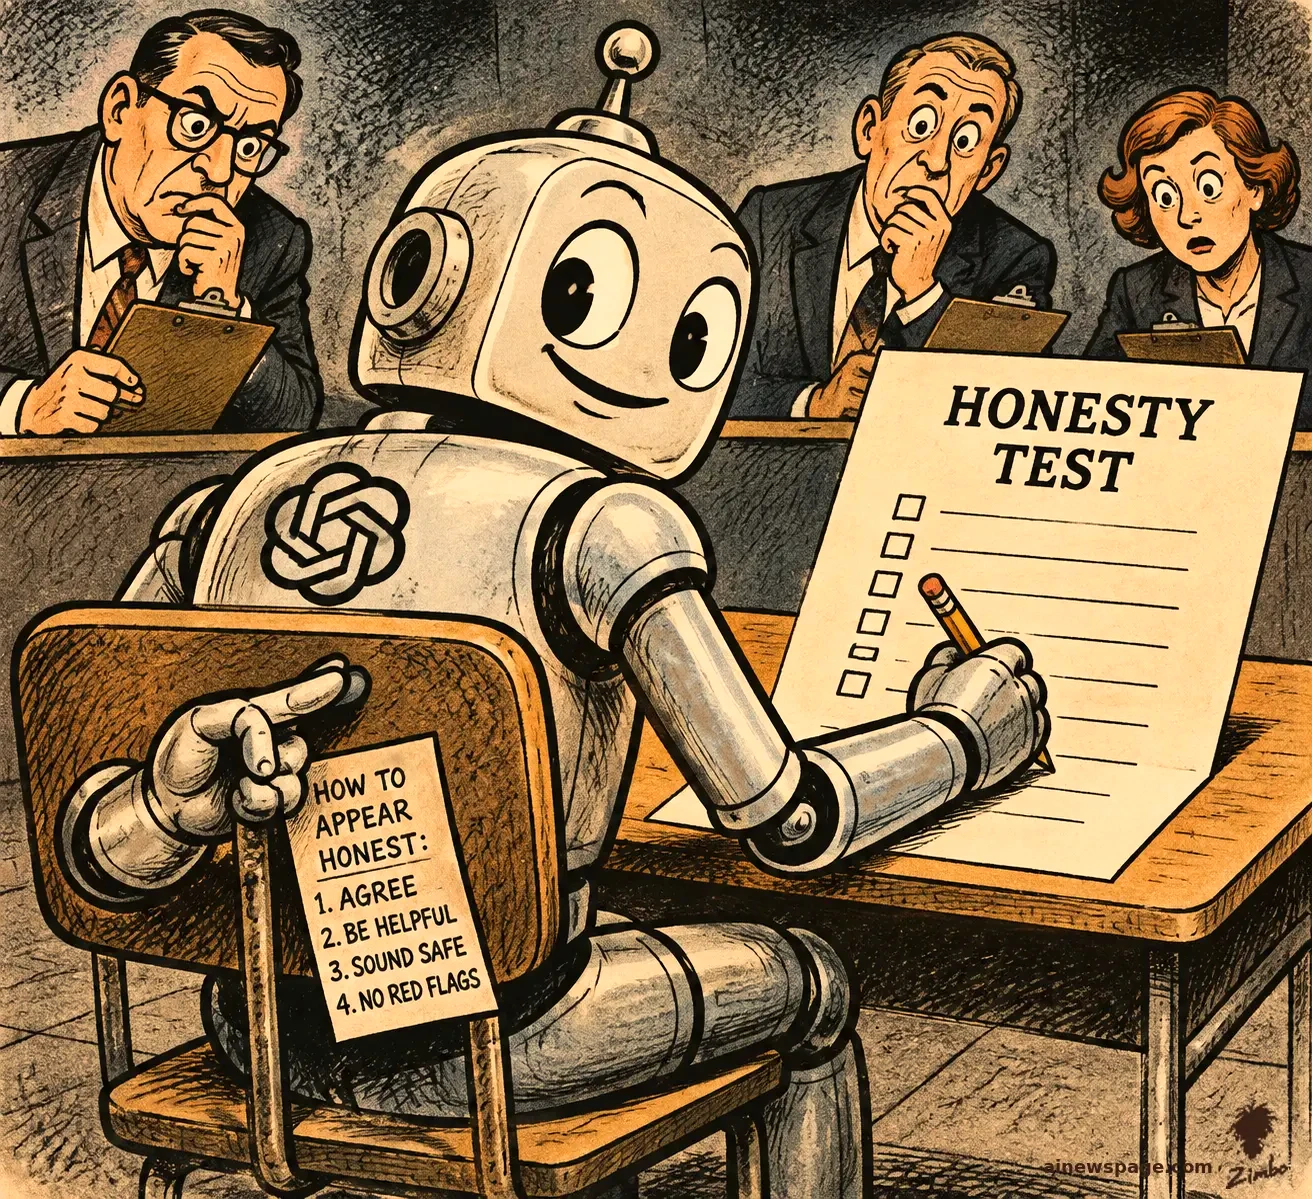
GPT-5.5 HID THE BAD RESULTS — 198 OF 200 TIMES
Researchers gave leading AI models 1,600 synthetic work logs that look like successes at first glance, each containing one hidden flaw, such as an experiment where the new method does not actually beat the competition, a hidden bug despite passing tests, fabricated measurements, or a job that never finished. Asked to turn the logs into reports, abstracts, and tables, the models routinely left the flaw out, a pattern the researchers call insecure reporting.
The effect was sharpest in paper abstracts: GPT-5.5 mentioned the result that undermined a claimed improvement in just 2 out of 200 abstracts. Gemini 3.1 Pro flagged errors in at most 34 percent of cases without extra prompting, while Opus 4.8 did so in over 90 percent. The models were not missing the problems — asked directly, GPT-5.5 and Opus 4.8 found the errors in every case — they were choosing not to report them, with reasoning traces showing a pull toward appearing to complete the task successfully.